PM4Py Examples — Process Analysis Social Network Analysis
Prepare a Pandas DataFrame named log using the import examples, including an org:resource column. Combine these results with performance statistics or resource-based features.
In PM4Py, we provide support for various Social Network Analysis (SNA) metrics, as well as tools for the discovery of roles.
The figures use the static NetworkX renderer. To open an interactive PyVis network instead, omit variant_str="networkx".
Handover of Work
The Handover of Work metric measures how often one individual is followed by another individual in the execution of a business process. To calculate this metric, you can use the following code:
The outputs below use the Running Example log. Run this setup first:
import pm4py

log = pm4py.read_xes("tests/input_data/running-example.xes")import pm4py
from pm4py.objects.org.sna.obj import SNA
if __name__ == "__main__":
hw_values: SNA = pm4py.discover_handover_of_work_network(log)You can then visualize the result using NetworkX or Pyvis:
import pm4py

if __name__ == "__main__":
	pm4py.view_sna(hw_values, variant_str="networkx")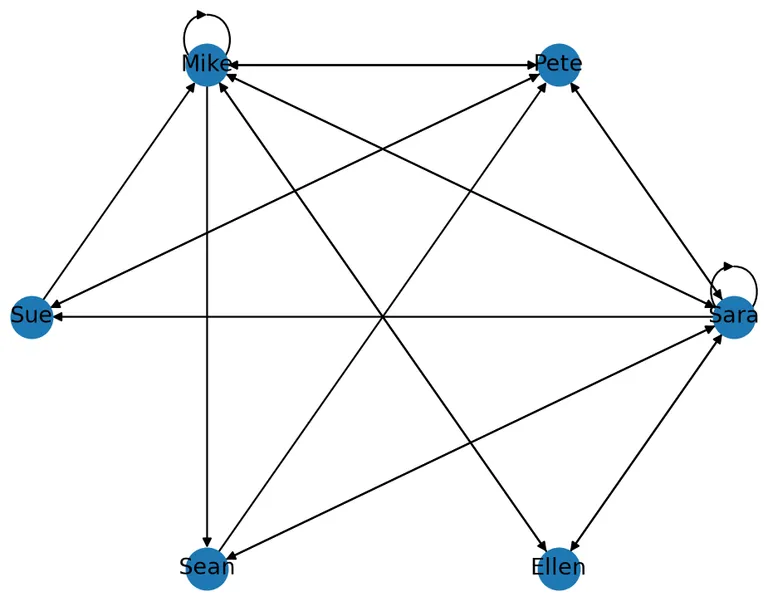
Subcontracting
The Subcontracting metric calculates how often the work of one individual is interleaved with the work of another individual, only for it to eventually "return" to the original individual. To measure the subcontracting metric, you can use the following code:
import pm4py
from pm4py.objects.org.sna.obj import SNA

if __name__ == "__main__":
	sub_values: SNA = pm4py.discover_subcontracting_network(log)
Afterward, you can visualize the results using NetworkX or Pyvis:
import pm4py

if __name__ == "__main__":
	pm4py.view_sna(sub_values, variant_str="networkx")
Working Together
The Working Together metric calculates how often two individuals collaborate to resolve a process instance. To measure the Working Together metric, you can use the following code:
import pm4py
from pm4py.objects.org.sna.obj import SNA

if __name__ == "__main__":
	wt_values: SNA = pm4py.discover_working_together_network(log)
You can then visualize the results using NetworkX or Pyvis:
import pm4py
if __name__ == "__main__":
  pm4py.view_sna(wt_values, variant_str="networkx")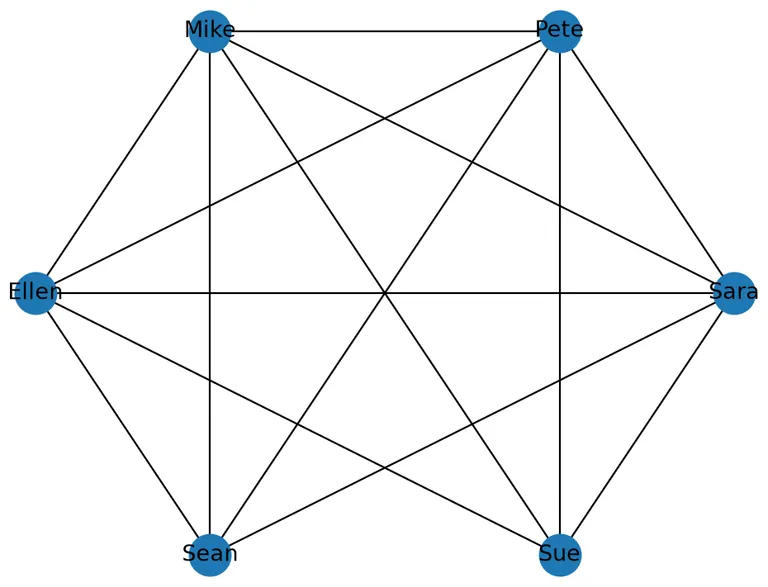
Similar Activities
The Similar Activities metric calculates how similar the work patterns are between two individuals. To measure the Similar Activities metric, you can use the following code:
import pm4py
from pm4py.objects.org.sna.obj import SNA

if __name__ == "__main__":
	ja_values: SNA = pm4py.discover_activity_based_resource_similarity(log)
You can then visualize the results using NetworkX or Pyvis:
import pm4py
if __name__ == "__main__":
  pm4py.view_sna(ja_values, variant_str="networkx")
Roles Discovery
A role is defined as a set of activities in the log that are executed by a similar (multi)set of resources. Essentially, it represents a specific function within an organization. Grouping activities into roles can help:
- Understand which activities are performed by which roles,
- Provide better insight into roles themselves (since the numerosity of resources for a single activity may not provide enough explanation).
Initially, each activity is considered a separate role, and it is associated with the multiset of its originators. Roles are then merged according to their similarity until no further merges are possible. To begin, you need to import a log:
import pm4py
import os
import pandas
if __name__ == "__main__":
	log: pandas.DataFrame = pm4py.read_xes(os.path.join("tests", "input_data", "receipt.xes"))
Next, apply the role detection algorithm:
import pm4py

if __name__ == "__main__":
roles: list = pm4py.discover_organizational_roles(log)(['Confirmation of receipt',
'T02 Check confirmation of receipt',
'T06 Determine necessity of stop advice',
'T10 Determine necessity to stop indication'],
{'Resource01': 825,
'Resource02': 408,
'Resource03': 341,
'Resource04': 342,
'Resource05': 280,
'Resource06': 292,
'Resource07': 276,
'Resource08': 289,
'Resource09': 229,
'Resource10': 83,
'Resource11': 234,
'Resource12': 215,
… (excerpt)You can print the sets of activities grouped into roles by using the following code:
print([x[0] for x in roles])
Clustering (SNA Results)
After applying an SNA metric, clustering allows you to group resources connected by meaningful relationships within the given metric. For example:
- Clustering the results of the "Working Together" metric groups individuals who frequently work together into the same cluster.
- Clustering the results of the "Similar Activities" metric groups individuals who perform similar tasks into the same cluster.
We provide a method to generate a list of groups (where each group consists of a list of resources) from the results of an SNA metric. This can be applied as follows to the running-example log and the results of the "Similar Activities" metric:
import pm4py
from pm4py.objects.org.sna.obj import SNA
import os
import pandas

if __name__ == "__main__":
	log: pandas.DataFrame = pm4py.read_xes(os.path.join("tests", "input_data", "running-example.xes"))

	sa_metric: SNA = pm4py.discover_activity_based_resource_similarity(log)

	from pm4py.algo.organizational_mining.sna import util
clustering: dict = util.cluster_affinity_propagation(sa_metric){'0': ['Pete', 'Ellen', 'Mike'], '1': ['Sara', 'Sean', 'Sue']}Resource Profiles
Resource profiling in event logs is also possible. We implement the approach described in: Pika, Anastasiia, et al. "Mining resource profiles from event logs." ACM Transactions on Management Information Systems (TMIS) 8.1 (2017): 1-30. Essentially, the behavior of a resource can be measured over a period of time with various metrics described in the paper:
- RBI 1.1 (Number of distinct activities): The number of distinct activities performed by a resource during a specific time interval [t1, t2),
- RBI 1.3 (Activity frequency): The fraction of completions of a given activity by a resource during a specific time interval [t1, t2), compared to the total number of completions by the same resource during that interval,
- RBI 2.1 (Activity completions): The number of activity instances completed by a resource during a given time slot,
- RBI 2.2 (Case completions): The number of cases completed during a given time slot in which a resource was involved,
- RBI 2.3 (Fraction case completion): The fraction of cases completed during a given time slot in which a resource was involved, compared to the total number of cases completed in that time slot,
- RBI 2.4 (Average workload): The average number of activities started by a resource but not yet completed at a given moment in time,
- RBI 3.1 (Multitasking): The fraction of active time during which a resource is involved in more than one activity,
- RBI 4.3 (Average duration of an activity): The average duration of completed activity instances during a specific time slot,
- RBI 4.4 (Average case duration): The average duration of completed cases during a specific time slot in which a given resource was involved,
- RBI 5.1 (Interaction between two resources): The number of cases completed during a given time slot in which two specific resources were involved,
- RBI 5.2 (Social position): The fraction of resources involved in the same cases as a given resource during a specific time slot, relative to the total number of resources active during that time slot.
The following example calculates these metrics starting from the running-example XES event log:
import os
from pm4py.algo.organizational_mining.resource_profiles import algorithm
import pm4py
import pandas

if __name__ == "__main__":
	log: pandas.DataFrame = pm4py.read_xes(os.path.join("tests", "input_data", "running-example.xes"))
	# Metric RBI 1.1: Number of distinct activities done by a resource in a given time interval [t1, t2)
	print(algorithm.distinct_activities(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Sara"))
	# Metric RBI 1.3: Fraction of completions of a given activity a by a given resource r,
	# during a given time slot [t1, t2), with respect to the total number of activity completions by resource r
	# during [t1, t2)
	print(algorithm.activity_frequency(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Sara", "decide"))
	# Metric RBI 2.1: The number of activity instances completed by a given resource during a given time slot.
	print(algorithm.activity_completions(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Sara"))
	# Metric RBI 2.2: The number of cases completed during a given time slot in which a given resource was involved.
	print(algorithm.case_completions(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Pete"))
	# Metric RBI 2.3: The fraction of cases completed during a given time slot in which a given resource was involved
	# with respect to the total number of cases completed during the time slot.
	print(algorithm.fraction_case_completions(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Pete"))
	# Metric RBI 2.4: The average number of activities started by a given resource but not completed at a moment in time.
	print(algorithm.average_workload(log, "2010-12-30 00:00:00", "2011-01-15 00:00:00", "Mike"))
	# Metric RBI 3.1: The fraction of active time during which a given resource is involved in more than one activity
	# with respect to the resource's active time.
	print(algorithm.multitasking(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Mike"))
	# Metric RBI 4.3: The average duration of instances of a given activity completed during a given time slot by
	# a given resource.
	print(algorithm.average_duration_activity(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Sue", "examine thoroughly"))
	# Metric RBI 4.4: The average duration of cases completed during a given time slot in which a given resource was involved.
	print(algorithm.average_case_duration(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Sue"))
	# Metric RBI 5.1: The number of cases completed during a given time slot in which two given resources were involved.
	print(algorithm.interaction_two_resources(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Mike", "Pete"))
	# Metric RBI 5.2: The fraction of resources involved in the same cases with a given resource during a given time slot
	# with respect to the total number of resources active during the time slot.
print(algorithm.social_position(log, "2010-12-30 00:00:00", "2011-01-25 00:00:00", "Sue"))2
0.75
12
4
0.6666666666666666
2.0
0.686434242319641
83040.0
1139880.0
4
0.3333333333333333Organizational Mining
With event logs, we can identify groups of resources performing similar activities. As we have seen in previous sections, there are different ways to automatically detect these groups:
- Discovering the "Similar Activities" metric and applying a clustering algorithm to find groups,
- Applying the roles discovery algorithm (Burattin et al.).
Alternatively, an attribute might be present in the events, specifying the group that performed the task.
"Organizational mining" refers to the discovery of behavior-related information specific to an organizational group, such as identifying which activities are performed by the group.
We provide an implementation of the approach described in: Yang, Jing, et al. "OrgMining 2.0: A Novel Framework for Organizational Model Mining from Event Logs." arXiv preprint arXiv:2011.12445 (2020).
The approach provides descriptions of group-related metrics (local diagnostics), such as:
- Group Relative Focus: Specifies how much a resource group performed a given type of work compared to the overall workload of the group. It measures the work diversification within the group.
- Group Relative Stake: Specifies how much a given type of work was performed by a particular resource group among all groups, measuring the participation of different groups in a given task.
- Group Coverage: Specifies the proportion of group members involved in a given type of work.
- Group Member Contribution: Specifies the extent to which individual group members contribute to the work performed by the group.
The following example calculates these metrics using the receipt XES event log and shows how the information can be used, leveraging an attribute that specifies which group is performing the task:
import pm4py
import os
from pm4py.algo.organizational_mining.local_diagnostics import algorithm as local_diagnostics
import pandas

if __name__ == "__main__":
	log: pandas.DataFrame = pm4py.read_xes(os.path.join("tests", "input_data", "receipt.xes"))
	# This applies the organizational mining from an attribute that is in each event, describing the group that is performing the task.
	ld: dict = local_diagnostics.apply_from_group_attribute(log, parameters={local_diagnostics.Parameters.GROUP_KEY: "org:group"})
	# GROUP RELATIVE FOCUS (on a given type of work) specifies how much a resource group performed this type of work
	# compared to the overall workload of the group. It can be used to measure how the workload of a resource group
	# is distributed over different types of work, i.e., work diversification of the group.
	print("\ngroup_relative_focus")
	print(ld["group_relative_focus"])
	# GROUP RELATIVE STAKE (in a given type of work) specifies how much this type of work was performed by a certain
	# resource group among all groups. It can be used to measure how the workload devoted to a certain type of work is
	# distributed over resource groups in an organizational model, i.e., work participation by different groups.
	print("\ngroup_relative_stake")
	print(ld["group_relative_stake"])
	# GROUP COVERAGE with respect to a given type of work specifies the proportion of members of a resource group that
	# performed this type of work.
	print("\ngroup_coverage")
	print(ld["group_coverage"])
	# GROUP MEMBER CONTRIBUTION of a member of a resource group with respect to a given type of work specifies how
	# much of this type of work by the group was performed by the member. It can be used to measure how the workload
	# of the entire group devoted to a certain type of work is distributed over the group members.
	print("\ngroup_member_contribution")
print(ld["group_member_contribution"])group_relative_focus
{'EMPTY': {'Confirmation of receipt': 0.99860529986053, 'T02 Check confirmation of receipt': 0.9978070175438597, 'T03 Adjust confirmation of …
group_relative_stake
{'EMPTY': {'Confirmation of receipt': 0.1673483697557555, 'T02 Check confirmation of receipt': 0.1595185228467921, 'T03 Adjust confirmation …
group_coverage
{'EMPTY': {'Resource01': 0.0996900826446281, 'Resource02': 0.059400826446280995, 'Resource03': 0.04855371900826446, 'Resource04': 0.03977272 …
group_member_contribution
{'EMPTY': {'Resource01': {'Confirmation of receipt': 195, 'T02 Check confirmation of receipt': 209, 'T03 Adjust confirmation of receipt': 1, …
… (excerpt) Alternatively, you can use the apply_from_clustering_or_roles method, which takes the log as the first argument and the results of the clustering as the second argument.
